7 Best Ways to Extract All Links from a Website
Discover 7 ways to use a link extractor to find website links with online tools, browser extensions, Python scripts, and SEO crawlers for faster link analysis now
Links are one of the foundational pieces of the modern web. Whether you need them to redirect users, guide crawlers, or drive traffic towards your other sites, having a way to find all available URLs on a single page or an entire domain comes up very often in the work.
Here are 7 ways to extract all URLs from a website, ranging from simple browser-based solutions requiring no technical skills to more advanced command-line utility approaches for large-scale crawling.
What Is a Link Extractor?
A link extractor is essentially a tool (or script) for parsing through the source code of a given web page and listing all the hyperlinks contained within it.
It analyses the HTML structure and finds all the hyperlinks and their anchor texts using the HTML’s href attribute of the anchor element. Most of these tools will give you a full list with all the URLs and allow you to copy them over or export them into a spreadsheet.
There are many different types of link extractors, ranging from some very basic web-based tools up to more sophisticated browser extensions or full-scale crawlers working on desktop PCs. Their scopes vary widely too – there are ones which only analyze one web page at a time, and then those which try to traverse a whole domain. Which one you pick comes down to how large your target website is, and how much data you need. Understanding website URLs can also help you organize and analyze links more effectively.
What Does It Mean to Extract All Links from a Website?
Extracting all links from a website means compiling all hyperlinks you can find within a web page – not just those that are visible, but also the hidden ones.
Typically, this will consist of internal and/or external (pointing towards other domains) links as well as references to images, scripts, stylesheets, downloadable files, etc. To do an exhaustive extraction, you’ll need a crawler to follow these links recursively or have someone repeat the whole thing for each individual page.
Method 1: Use an Online Link Extractor Tool
Web-based link extractors work faster than other options and allow you to analyze an entire page quickly. You won’t need any installations or tech configurations — they’re perfect for performing quick checks, especially if your team doesn’t have anyone with a dev background.
Here’s how it works:
- Open an online link extractor tool in a browser (e.g. Firecrawl).
- Enter the URL of the target page.
- Select the extraction options (internal links, external links, or both).
- Submit the request and review the list returned.
- Copy the results or download them in the available format.
The main limitation is scope. Most only allow you to analyse one page at a time with some restrictions on usage, and none of them can handle sites requiring authentication. They also may not parse pages properly if they contain content rendered via JavaScript.
Method 2: Use a Browser Extension
Browser extensions extract links directly from the page by scanning it. These types of tools typically allow for extracting links from pages a remote tool wouldn’t be able to reach (as well as pages behind a login or rendered dynamically), since they’re working inside your browser session. For example, an extension like Link Extractor collects all the links on the current page and exports them into a CSV file. Here’s how it works:
Install a “link extraction” extension from the Chrome Web Store.
- Navigate to the page that you want to scan.
- Run the extraction process.
- Download the list or copy it to the clipboard.
This method is good if you need results quickly. But most of the time, these extensions are limited to one page, so large-scale automation is not possible with an extension.
Method 3: Run a JavaScript Snippet in Your Browser Console
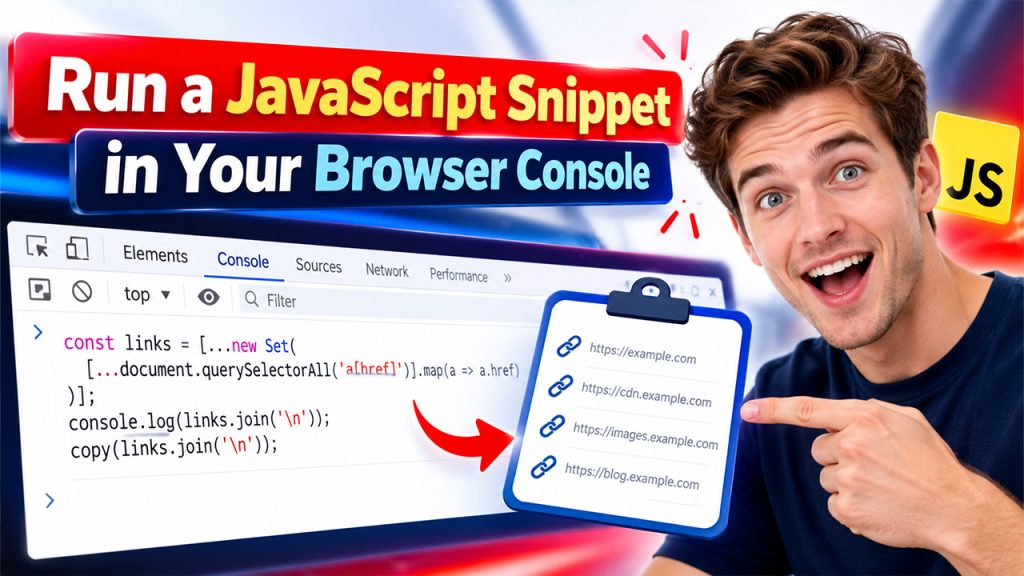
The browser developer console allows anyone to run a short script without installing any software. It does require programming skills, but it’s quick and completely free.
To use it, open the target page, press F12 or Ctrl+Shift+J, select the Console tab, and paste the following code:
const links = […new Set(
[…document.querySelectorAll(‘a[href]’)].map(a => a.href)
)];
console.log(links.join(‘\n’));
copy(links.join(‘\n’));
This script will collect all the anchors with an href property, convert them to absolute URLs, remove any duplicates by using a Set, print the resulting list, and copy it to your clipboard. Note that modern web browsers often show a warning when pasting code, just like for other types of scripts.
Method 4: Crawl the Whole Site with Screaming Frog
Related walkthrough
Free SSL Checker Tool by OutRight CRM | Check Website SSL Certificate Instantly
The Screaming Frog SEO Spider is one of the most popular desktop crawlers for technical SEO professionals.
It recursively follows all the links on your site (and those on other sites too) and then reports out all the data it finds – including every URL you’ve discovered, their associated status code, the anchor text they contain, and more.
While there’s a limited free version (which only lets you crawl up to 500 URLs), getting the full suite requires purchasing a license.
- Download and install the application.
- Enter the homepage URL in the address bar and select Start.
- Allow the crawl to finish, monitoring progress in the upper pane.
- Open the Bulk Export menu.
- Save the export as a CSV or Excel file.
This method is probably what you’re after if doing a complete audit on your site. This spidering tool will allow you to configure whether it respects or ignores robots.txt, sets how deep it goes into crawling, renders JS, etc.
Method 5: Use Google Sheets with the IMPORTXML Function
You could also use Google Sheets to retrieve these links using a single formula – if your team works with spreadsheets, then this could be something useful.
Once you have all of your links, they’ll be listed within individual cells, allowing you to easily sort, filter and share them.
In an empty cell, enter the following formula:
=IMPORTXML(“https://en.wikipedia.org/wiki/Alan_Turing “, “//a/@href”)
It requests that page, evaluates the XPath and gives back all the values contained in the ‘href’ attributes listed vertically. If we need links from multiple pages, then we can put individual URLs into different cells and refer to these cells in our formulas.
But since this function doesn’t run JS on the requested pages, we won’t get to see any links generated dynamically by some script.
Method 6: Write a Simple Python Script (for Developers)
Python gives you full control of the entire extraction process and integrates easily into your automated workflows.
The Requests library gets the page, while the beautifulsoup4 package handles the parsing of the HTML. Both are available on PyPI and can be installed using pip.
import requests
from bs4 import BeautifulSoup
from urllib.parse import urljoin
url = “https://www.example.com“
response = requests.get(url, timeout=10)
soup = BeautifulSoup(response.text, “html.parser”)
links = {urljoin(url, a[“href”]) for a in soup.find_all(“a”, href=True)}
for link in sorted(links):
print(link)
A quick look at the script shows that it requests the page, then iterates through each of its anchor elements. Using Python’s built-in “urljoin” function, it converts all relative links into their absolute URL form and removes duplicates from the list by writing them to a set.
Method 7: Use GNU Wget for Command-Line Crawling
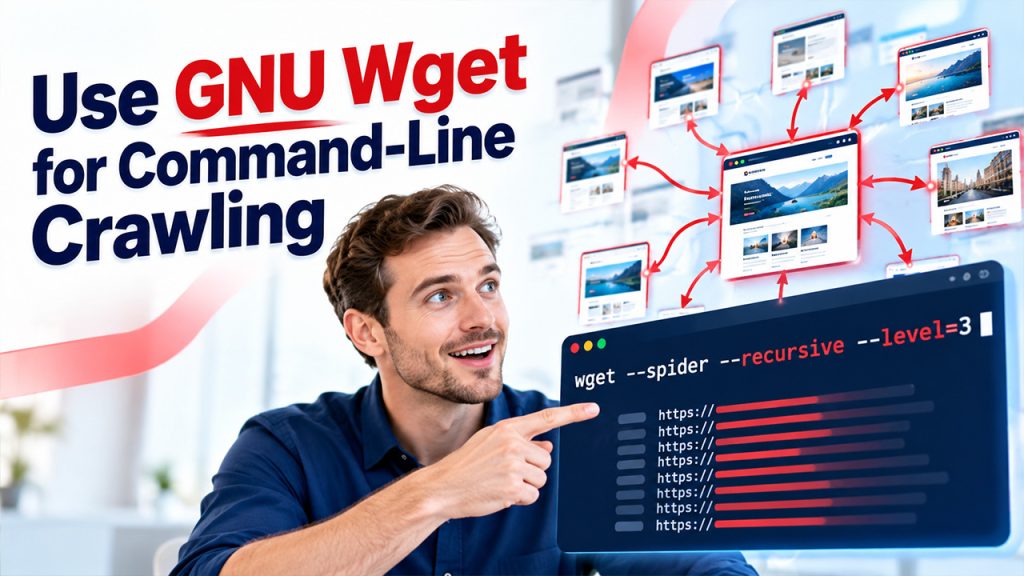
GNU Wget is a free command-line utility that works on Linux, macOS, and Windows. In spider mode, Wget will crawl your website but won’t save any of the pages. This can be useful if you’re trying to build an inventory of URLs on servers (and don’t want to download them), or if you’re using automation.
Run this command:
wget –spider –recursive –level=3 –no-verbose –output-file=crawl.log https://www.example.com
Now, to see what sites got crawled, you can run these commands, which will pull everything out of your log file into a links.txt file:
grep -oE ‘https?://[^ ]+’ crawl.log | sort -u > links.txt
Note that Wget doesn’t parse JavaScript – it just parses links found within the HTML downloaded. So if they have links hidden behind some JS code, you won’t find anything unless there’s also an href link included somewhere.
Quick Tips: Filtering, Deduplication, and Validation
Raw extraction output rarely suits analysis without further processing. Three practices improve its quality:
Step 1) Filter out internal vs. external links
You can do this by using a simple text filter for your primary domain in your spreadsheet. This helps when you want to review internal linking separately from outbound links.
Step 2) Get rid of duplicate URLs
There will be lots of repetition here (navigation menus/footer links are repeated across all pages). If you’re working with spreadsheets, there’s also a handy “remove duplicates” feature that does this automatically. Removing duplicates is a core part of data cleaning techniques.
Step 3) Check statuses
Just because a URL appears in this list doesn’t mean it works. Use tools to check if it’s a dead link or an active one.
Conclusion
Ultimately, choosing between data extraction tools, spreadsheet formulas vs Screaming Frog/python comes down to your goals, time & budget constraints, technical capabilities (if you’re planning on building custom scripts), etc.
In all cases, however – no matter which tool or methodology you pick – it’s important to filter/deduplicate/validate whatever dataset using data quality and validation best practices before acting on that data.
Frequently Asked Questions
The simplest way to extract all links is by using a browser extension or an online link extractor tool. They don’t require any coding.
Yes! You can use libraries like Beautiful Soup and requests to extract links from a website using Python.
Generally, you can extract publicly available links from a website without breaking any laws. But to be safe, we recommend that you review the website’s robots.txt file and terms of service before doing anything.
You would need a crawler like Screaming Frog or Scrapy that follows the internal links on your website.
Yes, you can export them using a tool or script. Many link extractors allow CSV export.